


raptor_crawl
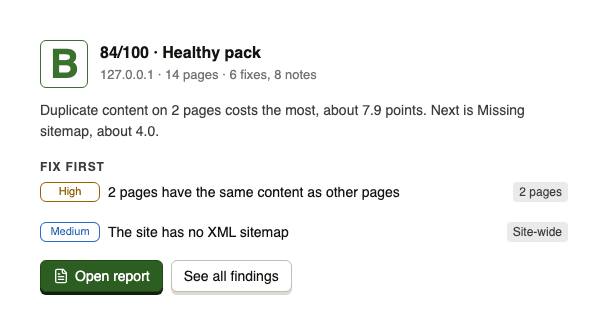
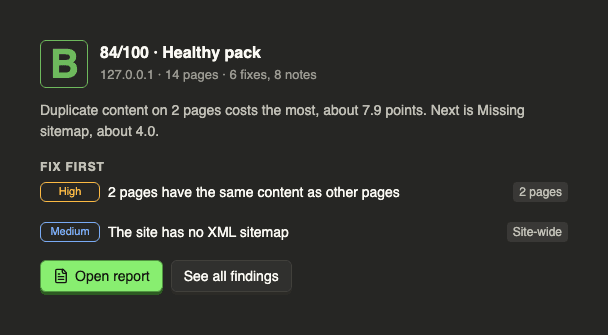
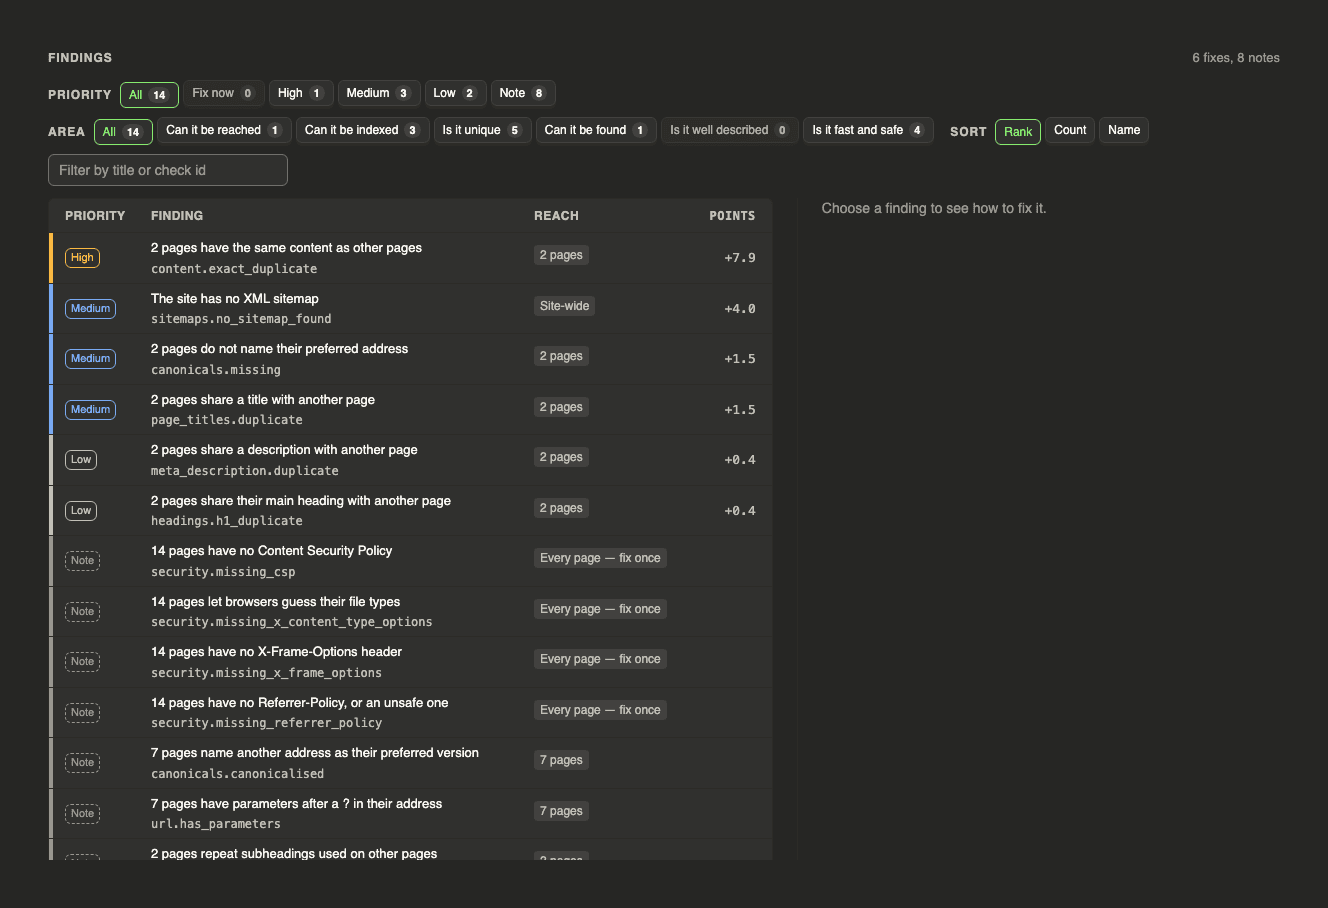
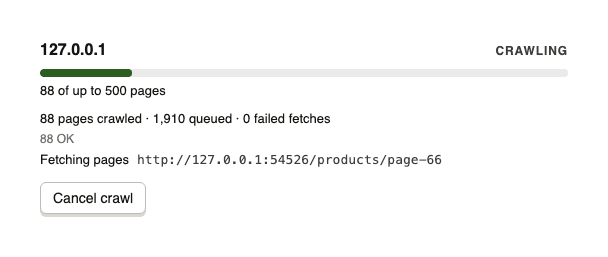
Crawl a siteStarts a jobStart a website crawl for SEO analysis. Returns a job_id to track progress. Use raptor_status to check when it completes, then raptor_summary and raptor_query to explore results. Where the host supports MCP Apps, shows live crawl progress.
Read-only: noDestructive: noIdempotent: noOpen world: yes
| Argument | Type | What it does |
|---|---|---|
urlrequired | string | The seed URL to begin crawling (e.g. https://example.com) |
backend | stringlocaldefault "local" | Crawl backend. Only 'local' is supported by the server; for JS-rendered crawls use the CLI. |
concurrency | integerdefault 3 | Number of concurrent requests (default: 3) |
delay_ms | integerdefault 250 | Delay between requests in milliseconds (default: 250) |
max_pages | integerdefault 500 | Maximum number of pages to crawl (default: 500) |
pagespeed | booleandefault false | Enable PageSpeed/Core Web Vitals analysis (default: false) |
pagespeed_sample | integer | Analyze only N random pages for PageSpeed (default: all) |
pagespeed_strategy | stringmobile | desktopdefault "mobile" | PageSpeed test strategy: 'mobile' (default) or 'desktop' |